GWの宿題的な何か
pypyのベンチマーク的な何か with Pillow(PIL)
# -*- coding:utf-8 -*-

import os
import re
import threading

from PIL import Image
from bs4 import BeautifulSoup

def transHue(img, huetype):
	img1 = img.copy()
	for hue in huetype.find_all(u"map"):
		c_from = [int(n.replace(u"*", u"-1")) for n in hue.get(u"from").split(u",")]
		c_to = [int(n.replace(u"*", u"-1")) for n in hue.get(u"to").split(u",")] + [255] # RGB + A
		try:
			c_idx = c_from.index(-1)
		except ValueError:
			c_idx = -1
		img2 = Image.new(u"RGBA", img1.size, (255, 0, 255, 0))
		for i in xrange(img1.size[0]):
			for j in xrange(img1.size[1]):
				img1_pixel = img1.getpixel((i,j))
				if ((c_from[0] == -1 and img1_pixel[0] > 0) or c_from[0] == img1_pixel[0]) \
					and ((c_from[1] == -1 and img1_pixel[1] > 0) or c_from[1] == img1_pixel[1]) \
					and ((c_from[2] == -1  and img1_pixel[2] > 0) or c_from[2] == img1_pixel[2]):
					if c_idx == -1:
	 					img2.putpixel((i, j), c_to)
					else:
						img2.putpixel((i, j), map(lambda n: ((n * img1_pixel[c_idx]) >> 8) + 1,  c_to))
				else:
					img2.putpixel((i, j), img1_pixel)
		img1.close()
		img1 = img2
	return img2

def decodeXml(filepath):
	re_ent = re.compile(u"<!ENTITY (.*?) '(.*?)'>", re.S)
	xml_raw = open(filepath).read().decode(u"cp932")
	xml_re = re_ent.findall(xml_raw)
	for group in xml_re or []:
		xml_raw = xml_raw.replace(u"&" + group[0] + u";", group[1])
	return xml_raw.lower()

class scrap:
	def __init__(self):
		self.pic_dic = {}
		self.img_list = []
		self.soup = None
		self.lock = threading.RLock()
		self.semaphore = threading.BoundedSemaphore(32)

	def load(self, xml_raw):
		self.soup = BeautifulSoup(xml_raw)
		for picture in self.soup.find_all(u"picture"):
			pic_path = picture.get(u"src")
			if pic_path:
				contribution = picture.find_parent(u"contribution")
				if contribution:
					self.pic_dic[contribution.get('id')] = os.path.join(path, pic_path.replace(u"/", u"\\"))

	def basename(self, sprite, path):
		picture = sprite.find(u"picture")
		file = picture.get(u"src")
		file = os.path.join(path, file) if file else self.pic_dic[picture.get(u"ref")]
		return file

	def crop(self, sprite, size, filepath, opposite):
		org_x, org_y = [int(n) for n in sprite.get(u"origin").split(u",")]
		size_x, size_y = [int(n) for n in size.text.split(u",")]
		if opposite: size_x, size_y = size_y, size_x
		offset = int(sprite.get(u"offset"))
		img = Image.open(filepath).convert(u"RGB")
		base = Image.new(u"RGBA", img.size, (255, 0, 255, 0))
		base.paste(img, (0, 0))
		img.close()
		return base.crop((org_x, org_y, org_x + (size_x + size_y) * 16, org_y + offset + (1 + size_y) * 8))

	def color(self, contribution, sprite, img, file):
		huetype = sprite.find(u"spritetype")
		if huetype:
			img_hue = transHue(img, huetype)
			img.close()
			self.lock.acquire()
			print "|>",
			self.img_list.append((img_hue, file))
			self.lock.release()
		else:
			huetypes = contribution.find_all(u"spritetype")
			if huetypes:
				for huetype in huetypes:
					img_orig = img.copy()
					img_hue = transHue(img_orig, huetype)
					img_orig.close()
					self.lock.acquire()
					print "/>",
					self.img_list.append((img_hue, file))
					self.lock.release()
				img.close()
			else:
				self.lock.acquire()
				print "->",
				self.img_list.append((img, file))
				self.lock.release()

	def parse(self, path):
		threads = []
		event = threading.Event()
		for contribution in self.soup.find_all(u"contribution"):
			thread = threading.Thread(target=self.encode, args=(path, contribution))
			thread.start()
			threads.append(thread)
		for thread in threads:
			thread.join()

	def alpha(self, img1):
		img2 = Image.new(u"RGBA", img1.size, (255, 0, 255, 0))
		for i in xrange(img1.size[0]):
			for j in xrange(img1.size[1]):
				img1_pixel = img1.getpixel((i, j))
				if 255 == img1_pixel[0] and 0 == img1_pixel[1] and 255 == img1_pixel[2]:
					img2.putpixel((i, j), (255, 0, 255, 0))
				else:
					img2.putpixel((i, j), img1_pixel + (255,))
		img1.close()
		return img2

	def tower(self, stack, size, path, opposite, floor_max):
		imgs = [self.alpha(self.crop(sprite, size, self.basename(sprite, path), opposite)) for sprite in stack]
		# MAX(MIDDLE_HEIGHT + BOTTOM_HEIGT + TOP_HEIGHT)
		height_max = max([imgs[1].size[1] + 16 * floor for floor in xrange(1, floor_max + 1)] \
							+ [imgs[2].size[1], imgs[0].size[1] + 16 * (floor_max + 1)])
		background = Image.new(u"RGBA", (imgs[2].size[0], height_max), (255, 0, 255, 0))
		# BOTTOM
		background.paste(imgs[2], (0, background.size[1] - imgs[2].size[1]), mask=imgs[2].split()[3])
		# MIDDLE
		for floor in xrange(1, floor_max + 1):
			background.paste(imgs[1], (0, background.size[1] - imgs[1].size[1] - 16 * floor), mask=imgs[1].split()[3])
		# TOP
		background.paste(imgs[0], (0, background.size[1] - imgs[0].size[1] - 16 * (floor_max + 1)), mask=imgs[0].split()[3])
		return background, self.basename(stack[-1], path)

	def encode(self, path, contribution):
		self.semaphore.acquire()
		try:
			size = contribution.find(u"size")
			if size:
				sprite_list = contribution.find_all(u"sprite")
				if sprite_list:
					for sprite in sprite_list:
						opposite = sprite.get(u"opposite") != None
						filepath = self.basename(sprite, path)
						self.color(contribution, sprite, self.crop(sprite, size, filepath, opposite), filepath)
				else:
					height_min = contribution.find(u"minheight")
					height_min = int(height_min.text) if height_min else 2
					height_max =  contribution.find(u"maxheight")
					height_max = int(height_max.text) if height_max else 5
					pictures_list = contribution.find_all(u"pictures")
					if pictures_list:
						for pictures in pictures_list:
							opposite = pictures.get(u"opposite") != None
							stack = [pictures.find(key) for key in [u"top", u"middle", u"bottom"]]
							if not None in stack:
								img, file = self.tower(stack, size, path, opposite, height_max - height_min)
								self.color(contribution, pictures, img, file)
		except Exception as e:
			self.lock.acquire()
			print "Error:", str(type(e)), e.message, contribution
			self.lock.release()
		self.semaphore.release()

def makeTile(img_list, prefix):
	class img_set:
		def __init__(self, img1, size1):
			self.img = img1
			self.x, self.y = size1
	img_size = {}
	for img, file in img_list:
		if file not in img_size: img_size[file] = (0, 0)
		if img_size[file][1] < img.size[1]: img_size[file] = img.size

	img_type = {}
	for img, file in img_list:
		key = "_".join([str(s) for s in img_size[file]])
		if key not in img_type: img_type[key] = []
		img_type[key].append(img_set(img, img_size[file]))

	for filename, val1 in img_type.items():
		width = val1[0].x
		base = Image.new(u"RGB", (width * len(val1), val1[0].y), (255, 0, 255))
		for idx, val2 in enumerate(val1):
			base.paste(val2.img, (width * idx, val1[0].y - val2.img.size[1]))
		if width > 0: base.save(prefix + filename + u".bmp")
		base.close()

def dirs(directory):
	for root, dirs, files in os.walk(directory):
		yield root, None
		for file in files:
			yield root, file

if __name__ == '__main__':
	for path, file in dirs(u"."):
		if file == "plugin.xml":
			preload = scrap()
			preload.load(decodeXml(os.path.join(path, file)))
	for path, file in dirs(u"."):
		if file == "plugin.xml":
			imgs = scrap()
			imgs.pic_dic = preload.pic_dic
			imgs.load(decodeXml(os.path.join(path, file)))
			imgs.parse(path)
			makeTile(imgs.img_list, path.lower().replace(u"\\", u"_").replace(u".", u"_").replace(u"__", u"") + u"_")
【マスクとアドレスと論理式】pythonでのbit演算でIPv4を計算する
何コレ?
#! /usr/bin/env python
# -*- coding: utf-8 -*-

import sys
import socket
import struct
import re

type1 = re.compile(ur'([\d\.]+)\/(\d+)') # 192.168.0.1/24
type2 = re.compile(ur'([\d\.]+)\s+([\d\.]+)') # 192.168.0.1/ 255.255.255.0

acl_serach_max = 8192
acl_search_ip_max = 4

def aton(ipstr):
	return struct.unpack(r'!l', socket.inet_aton(ipstr))[0]

def ntoa(ip):
	return socket.inet_ntoa(struct.pack(r'!l', ip))

def net_addr(ip_addr, subnet):
	return (ip_addr & subnet)

def bcast_addr(ip_addr, subnet):
	return ip_addr | ~subnet

def bit_mask(bit):
	if 32 <= bit:
		bin = r'0'
	elif bit <= 0:
		bin = r'1' * 32
	else:
		bin = r'1' * (32 - bit)
	return ~int(bin, 2)

def check_subnet(ip_addr, subnet, ip):
	if ((ip & subnet) ^ (ip_addr & subnet)) == 0:
		return True
	else:
		return False

def check_wildcard(ip_addr, wildcard, ip):
	if ((ip & ~wildcard) ^ (ip_addr & ~wildcard)) == 0:
		return True
	else:
		return False

def count_wildcard(ip_start, ip_end, wildcard):
	if not bin(wildcard).lstrip(r'0b').find(r'0') == -1:
		i = 0
		ip_addrs = []
		for ip in xrange(ip_start, ip_end+1):
			if check_wildcard(ip_start, wildcard, ip):
				ip_addrs.append(ntoa(ip))
			i += 1
			if i > acl_serach_max or len(ip_addrs) >= acl_search_ip_max:
				ip_addrs.append(r"...")
				break
		return ip_addrs
	else:
		return (ip_end - ip_start) + 1

def parse(ip, mask):
	if 0 < mask:
		# net_addr
		wildcard_start = ip & ~mask
		# bcast_addr
		wildcard_end = ip | mask
		print r'ACL',
		print ntoa(ip), r'->', ntoa(wildcard_start), r'-', ntoa(wildcard_end), count_wildcard(wildcard_start, wildcard_end, mask)
	else:
		if check_subnet(aton(r'10.0.0.0'), aton(r'255.0.0.0'), ip):
			print r'PrivateA',
		elif check_subnet(aton(r'172.16.0.0'), aton(r'255.240.0.0'), ip):
			print r'PrivateB',
		elif check_subnet(aton(r'192.168.0.0'), aton(r'255.255.0.0'), ip):
			print r'PrivateC',
		elif check_subnet(aton(r'169.254.0.0'), aton(r'255.255.0.0'), ip):
			print r'APIPA',
		elif check_subnet(aton(r'224.0.0.0'), aton(r'240.0.0.0'), ip):
			print r'Multicast',
		else:
			print r'Global',
		net = net_addr(ip, mask)
		bcast = bcast_addr(ip, mask)
		print ntoa(ip), r'->', ntoa(net), r'/', ntoa(mask), ntoa(bcast), (bcast - net) + 1

def entry():
	print r'[[ IP Range 1.0.0 ]]'
	for line in iter(sys.stdin.readline, r''):
		try:
			line = line.strip()
			rr = type1.findall(line)
			for sIp, sMask in rr:
				ip = aton(sIp)
				mask = bit_mask(int(sMask))
				parse(ip, mask)
			line  = type1.sub(r'', line)
			rr = type2.findall(line)
			for sIp, sMask in rr:
				ip = aton(sIp)
				mask = aton(sMask)
				parse(ip, mask)
		except socket.error, e:
			print 'Syntax Error:', e
		except (ee, e):
			print 'Error:', ee, e

if __name__ == '__main__':
	reload(sys)
	sys.setdefaultencoding(r'utf-8')
	entry()
簡単に言えばIPアドレスのレンジを計算してくれる計算機だ。
もちろんpythonで書いた。
いやー、持ち込み何でも可っていうのはイイネ!
どんな計算機?
ネットワークアドレス、サブネットマスク、ブロードキャスト、IPの数がスパッとわかる。
[[ IP Range 1.0.0 ]]
192.168.10.245/24[エンター]
PrivateC 192.168.10.245 -> 192.168.10.0 / 255.255.255.0 192.168.10.255 256
172.16.32.254/12[エンター]
PrivateB 172.16.32.254 -> 172.16.0.0 / 255.240.0.0 172.31.255.255 1048576
もちろん複数行や表記ゆれ、CIDRにも対応
10.0.0.10/16 192.168.7.5 255.255.255.248 172.23.12.5/24[エンター]
PrivateA 10.0.0.10 -> 10.0.0.0 / 255.255.0.0 10.0.255.255 65536
PrivateB 172.23.12.5 -> 172.23.12.0 / 255.255.255.0 172.23.12.255 256
PrivateC 192.168.7.5 -> 192.168.7.0 / 255.255.255.248 192.168.7.7 8
しかもACLのワイルドカードマスクまで計算してくれるスグレもの
192.168.0.0 0.0.0.255 192.168.32.14 0.0.255.255[エンター]
ACL 192.168.0.0 -> 192.168.0.0 - 192.168.0.255 256
ACL 192.168.32.14 -> 192.168.0.0 - 192.168.255.255 65536
マスクとアドレスと論理式
そもそもアドレスだのマスクだのパソコンの都合がいい値を無理に表示して192.168.1.1だの255.255.255.0だのしてる訳であってIPv6の省略記法なんてすぐには覚えれそうに無イネ!
それでもアドレスとサブネットマスクからネットワークアドレスを求めてみる
まずは2進数で計算だ。そんな簡単な事を言うがHaskhellとかSchemeをやってそうな関数型言語を扱う高等民族とかとは別の至高なプログラマ、バイナリアンにしか直ぐには計算できない芸当であろう。
    10101100.00010000.00011100.11101011 # 172.16.28.235(IPアドレス)
AND 11111111.11111111.11111111.11111000 # 255.255.255.248(サブネット)
---------------------------------------
    10101100.00010000.00011100.11101000 # 172.16.28.232(ネットワーク)

    network_address = ip_address & subnetmask # プログラムで表すと…
ANDで計算すればサクっとできる!そんな簡単な事を言うが(略)
ブロードキャストは?
    10101100.00010000.00011100.11101011 # 172.16.28.235(IPアドレス)
OR  00000000.00000000.00000000.00000111 # 0.0.0.7(サブネットのインバース)
---------------------------------------
    10101100.00010000.00011100.11101111 # 172.16.28.239(ブロードキャスト)

    broadcast_address = ip_address | ~subnetmask # プログラムで表すと…
サブネットマスクをNOTでインバース(0と1を反転したもの)とし、IPアドレスとORしたものがブロードキャストだ。
しかし馬鹿な俺は最初にプログラムで書いたのが…
network_address = ip_address & subnetmask
broadcast_address = network_address + ~subnetmask
まだ俺は至高民族バイナリアンにはなれそうにないです。
式と範囲とワイルドカード
ワイルドカードマスクってなんぞや?簡単に言わせればワイルドカードマスクはサブネットマスクのインバースだ。(嘘)よってワイルドカードマスクの範囲はワイルドカードマスクを反転したものをサブネットとしてネットワークアドレスから始まりでブロードキャストアドレスで終わる簡単な物だ。(嘘)
172.16.28.235 0.0.0.7[エンター]
ACL 172.16.28.235 -> 172.16.28.232 - 172.16.28.239 8
172.16.28.235 0.0.3.255[エンター]
ACL 172.16.28.235 -> 172.16.28.0 - 172.16.31.255 1024
だがちょっと待って欲しい。ワイルドカードをもっと知るためにはサブネットマスクについてもっと知っておく必要がある。
10000000.00000000.00000000.00000000 # /1
                ...
11111111.00000000.00000000.00000000 # /8
                ...
11111111.11111111.11111111.00000000 # /24
                ...
11111111.11111111.11111111.11111000 # /29 255.254.255.248

左から右に1が増えていく…
サブネットマスクの最小クラスは/1である。そこから左から右に向かって埋まっていく。よって32ビット符号付き整数で表すとサブネットマスクは必ずマイナス値である。その符号の部分がサブネットマスクで表した時の128.000.000.000の128の部分になる。ここで重要な事が一つある。上の表を見て気づいたかもしれないが、サブネットマスクは1で埋まったところに0が紛れることは絶対に起きない。
11111111.11111111.11111111.11111 0 10 # 255.255.255.250 このような値にもならない。
                                ↑
11111111.1111111 0 .11111111.11111000
↑絶対に0が紛れるようなことは起きない。サブネットマスクでは以上のようなケースは絶対に起きないということだ。しかしワイルドカードマスクは違う、もう入らないなんてもんじゃない。超入る。とにかくワイルドカードマスクのヤバさをもっと知るべきだと思います。(この部分を書きたいためにこの記事書きました。)
ワイのワイルドカードなワイバーンや!
ということは以下のようなワイルドカードマスクも設定できるのである。
00000000.00000000.00000001.00001000 # 0.0.1.4
↑ 1と1の間に0が挟まれている以上のワイルドカードマスクを見て、もし(192.168.1.0 0.0.1.4)とかいう設定をACLでみしまったときアナタはどうするだろう。192.168.0.0〜192.168.1.4とかいうアナタは痛い目にみるかもしれない。正解は(192.168.0.0, 192.168.0.4, 192.168.1.0, 192.168.1.4)の4つだけである。
ACLのやっている処理を探る
    11000000.10101000.00000001.00000000 # 192.168.1.0(IPアドレス)
AND 11111111.11111111.11111110.11110111 # 0.0.1.4(ワイルドカードのインバース)
---------------------------------------
    11000000.10101000.00000000.00000000 # 192.168.0.0
まずACLの範囲はACLに設定されたIPアドレスにワイルドカードのインバースにANDを施したアドレスを求める。(実質、指定したIPアドレスのネットワークアドレスを求めたモノと同じ)
    11000000.10101000.00000001.00000011 # 192.168.1.3(192.168.0.0〜192.168.1.4の間にありそうなIP)
AND 11111111.11111111.11111110.11110111 # 0.0.1.4(ワイルドカードのインバース)
---------------------------------------
    11000000.10101000.00000000.00000011 # 192.168.0.3
次にチェックされるIPアドレスに同じようにワイルドカードのインバースをANDで施したアドレスを求め、上で求めたアドレスと比較し合致するか合致しないかを判定するのだ。(実質的に、上のアドレスとネットワークアドレスが違ってしまった!これでは別ネットワークと判断される)
わかりやすく…?
最初の処理でしているのは…
11000000.10101000.00000001.00000000 # 192.168.1.0(IPアドレス)
00000000.00000000.00000001.00001000 # 0.0.1.4(ワイルドカード)
11000000.10101000.0000000*.0000*000 # *の部分だけ無視することができる
そしてチェックするIPと比べてみると…
11000000.10101000.00000001.00000011 # 192.168.1.3
11000000.10101000.0000000*.0000*000 #
                                 ↑*以外の部分が違っている!!
2つのビットの比較はコンピュータではXORでサクッと調べることが出来る。0が帰ってきたら正解だ。
((ip & subnet) ^ (ip_addr & subnet)) # サブネットマスクによる同一ネットワークのチェック
((ip & ~wildcard) ^ (ip_addr & ~wildcard)) # ワイルドカードによるチェック
偶数だけ、奇数だけのACLの種明かし
そんな狂気じみたACLを設定して視認性が〜とかなる前にこれを応用したのが奇数だけ偶数だけのACLの設定方法である。
11000000.10101000.00000001.00000000 # 192.168.1.0(IPアドレス、最後が偶数でビットは0)
00000000.00000000.00000000.11111110 # 0.0.0.254(ワイルドカード)
11000000.10101000.00000001.*******0 # チェックするIPの最後のビットが0の時だけ判定される
                              ↑*の部分の判定は行われない。
最後のビットが0かどうかが判断され、また最後のビットが0の値は偶数だ。
11000000.10101000.00000001.00000001 # 192.168.1.1(IPアドレス、最後が偶数でビットは0)
00000000.00000000.00000000.11111110 # 0.0.0.254(ワイルドカード)
11000000.10101000.00000001.*******1 # チェックするIPの最後のビットが1の時だけ判定される
また最後のビットが1の値はなのは偶数だけである。以上でワイルドカードはサブネットマスクのインバースでなくフラグとしてのマスクであることを理解してくれれば嬉しい。
最後に
この記事は現在CCNAも取ってない状態で記述されました(´・ω・`)
オフラインでGCCを使ったmbed開発環境を作る。(第二版)
mbedって何ぞや?
NXP LPC1768のARMのMPUにブレッドボードで使いやすい足が生えて簡単にファームウェアを焼くことができるUSBクライアントポートがついたお手軽マイコン。
ADC/CAN/DAC/イーサネット/DMA/外部割込み/GPIO/I2C/I2S/PWM/RTC/SPI/SSP/UART/WDT/USBホスト/USBクライアントなど機能が盛りだくさん。
ただしハードウエアDSPは持ってません。(乗算除算のみ)
しかし、このmbedはWeb上からコンパイルを行うためにネット環境がなかったりPCのスペックやブラウザのバージョンが低かったりすると色々と問題なのでオフラインでエディタかIDEとmakeで開発したい…。
というときのための私的なメモです。
ちなみにこの開発環境はLPC1769の乗ったLPCXpressoにも対応してたりします。というかまんま上位互換です。
必要なソフトウエア
- コンパイラ: Sourcery G++ Lite for ARM EABI
- http://www.codesourcery.com/sgpp/lite/arm
- arm-2010q1-188-arm-none-eabi.exe以前を推奨、これより新しいコンパイラはlibcs3ライブラリが欠損してNXP謹製のリンカスクリプトでは正常にコンパイルできません。
- CMSIS: LPC175x and LPC176x CMSIS-Compliant Standard Peripheral Firmware Driver Library (GNU, Keil, IAR)
- http://ics.nxp.com/support/documents/microcontrollers/?scope=LPC1769
- lpc17xx.cmsis.driver.library.zip
CMSISから必要なファイルを抽出、そして修正を行う。
- \lpc17xx.cmsis.driver.library\Core\CM3\CoreSupport から
- core_cm3.c
- core_cm3.h
- core_cmFunc.h
- core_cmInstr.h
- \lpc17xx.cmsis.driver.library\Core\CM3\DeviceSupport\NXP\LPC17xx から
- LPC17xx.h
- system_LPC17xx.c
- system_LPC17xx.h
- \lpc17xx.cmsis.driver.library\Core\CM3\DeviceSupport\NXP\LPC17xx\startup\gcc から
- startup_LPC17xx.s
- \lpc17xx.cmsis.driver.library\makesection\makerule\example から
- ldscript_rom_gnu.ld
以上のファイルをひとつのフォルダに設置してください。
Makefileを作る。
#  Project Name
PROJECT=mbed_test

#  List of the objects files to be compiled/assembled
OBJECTS=startup_LPC17xx.o core_cm3.o system_LPC17xx.o $(PROJECT).o
LSCRIPT=ldscript_rom_gnu.ld
OPTIMIZATION = s -fno-schedule-insns2 -fsection-anchors -fpromote-loop-indices -ffunction-sections -fdata-sections
#DEBUG = -g

#  Compiler Options
GCFLAGS = -Wall -mcpu=cortex-m3 -mfloat-abi=softfp -mthumb -mfix-cortex-m3-ldrd -O$(OPTIMIZATION) $(DEBUG)
GCFLAGS += -D__RAM_MODE__=0
LDFLAGS = -mcpu=cortex-m3 -mfloat-abi=softfp -mthumb -mfix-cortex-m3-ldrd -O$(OPTIMIZATION) -Wl,-Map=$(PROJECT).map -T$(LSCRIPT)
ASFLAGS = -mcpu=cortex-m3 --defsym RAM_MODE=0

#  Compiler/Assembler/Linker Paths
GCC = arm-none-eabi-gcc
AS = arm-none-eabi-as
LD = arm-none-eabi-ld
OBJCOPY = arm-none-eabi-objcopy
OBJDUMP = arm-none-eabi-objdump
REMOVE = rm -f
SIZE = arm-none-eabi-size

#########################################################################

all:: $(PROJECT).hex $(PROJECT).bin $(PROJECT).lss

$(PROJECT).lss: $(PROJECT).elf
	$(OBJDUMP) -h -S $(PROJECT).elf > $(PROJECT).lss

$(PROJECT).bin: $(PROJECT).elf
	$(OBJCOPY) -O binary -j .text -j .data $(PROJECT).elf $(PROJECT).bin

$(PROJECT).hex: $(PROJECT).elf
	$(OBJCOPY) -R .stack -O ihex $(PROJECT).elf $(PROJECT).hex

$(PROJECT).elf: $(OBJECTS)
	$(GCC) $(LDFLAGS) $(OBJECTS) -o $(PROJECT).elf

stats: $(PROJECT).elf
	$(SIZE) $(PROJECT).elf

clean:
	$(REMOVE) $(OBJECTS)
	$(REMOVE) $(PROJECT).bin
	$(REMOVE) $(PROJECT).elf
	$(REMOVE) $(PROJECT).hex
	$(REMOVE) $(PROJECT).lss
	$(REMOVE) $(PROJECT).map

#########################################################################
#  Default rules to compile .c and .cpp file to .o
#  and assemble .s files to .o

.c.o :
	$(GCC) $(GCFLAGS) -c $<

.cpp.o :
	$(GCC) $(GCFLAGS) -c $<

.S.o :
	$(AS) $(ASFLAGS) -o $@ $<

#########################################################################
上記をコピーアンドペーストしてMakefileを作成してください。
最後に
あとはMakefileのPROJECTで指定した名前のソースファイル、ここではmbed_test.cppを作成し、
#include "LPC17xx.h"

volatile unsigned long tick;

extern "C"
{
	void SysTick_Handler(void)
	{
		tick++; // 1ms Tick...
	}
}

int main(void)
{
	SysTick_Config(SystemCoreClock/1000 - 1);

	/* ... */

	return 0;
}
ではじめることができます。
気を付けなければならないことは拡張子がcppつまり、C++でコンパイルした場合において割り込みハンドラはC言語による関数宣言をしておかないと呼出規約のせいかスタックの取り方がちがうのか正常に動作にしません。
あと、ペリフェラルのライブラリは
- \lpc17xx.cmsis.driver.library\Drivers
にありますので適宜インクルードしてコードをOBJECTSに追加してください。あとはMakeすればコンパイルできるはず。
予断ですが、CodeSourceryのコンパイラのlibcはnewlibを使っているみたいですね。組み込みでまともなstdio.hとstrings.hが手に入るのは強力だと思います。
devkitpro環境を作るために必死でパッチをあてbinutils,gcc,newlibをコンパイルした時代と比べれば楽な世の中になりましたね。
mbed.hなどは
とかでソースがダウンロードはできるもののARM謹製のコンパイラでlibcなどのシステムコールの実装が大きく違っているので流用できません。
pythonのmultiprocessingを使ってみた。 〜失敗編〜
自分はスクリプトではpythonが好きだ。処女はBashとDOS Batch Fileで果てたが初めてのインタプリタはCと相性の良いと聞いたPerlにしようかと思ったが、当時のPerlの参考となるスクリプトが汚くてセキュリティ的にもボロボロで、CGIにいたっては開発しにくい上にprint文でhtml出力している部分を見てしまった時には愛想が尽きてしまっていた。
結局、CGIに関してはPHP、スクリプトはPythonに落ち着いたのだがpython3.xが出ても依然とpython2.5を愛用している。ライブラリ依存的な意味でだ。pydが憎い。あぁ、CPythonよ、なぜ柵(さく)と柵(しがらみ)は同じ字なのだろう。
というわけで、最近ではRHEL6/CentOS6ではpythonをアンインストールするとカーネルまでアンインストールされるぐらいOSと密都合しているCPythonですが、JITなPyPyやGIL問題とか気にしてIronPythonに浮気をするついでにVersion2.6以降multiprocessingに触れてみようとおもった。余談だが、IronPythonは起動が重すぎ。
そもそもスレッドとプロセス問題なんてC/C++ with Linuxで散々悩み通った道だ、worker(スレッド)とfork(プロセス)がどうたらこうたらなんて今更感がしなくもないということでpyDoc眺めつつサクっと書いてみたのが以下である。
#! /usr/bin/env python
# -*- coding: utf-8 -*-

try:
	import multiprocessing as _threading
	from multiprocessing import Process as _thread
except ImportError:
	import threading as _threading
	from threading import Thread as _thread

class Async:
	def __init__(self, concurrent=1):
		self.lock = _threading.BoundedSemaphore(concurrent)

	def __call__(self, callBack, errorBack, **kwargs):
		def deferred():
			try:
				callBack(**kwargs)
			except Exception, errors:
				errorBack(errors, callBack, **kwargs)
			finally:
				self.lock.release()
		self.lock.acquire()
		thread = _thread(target=deferred)
		thread.start()
自分は関数内で関数を宣言するのは好きだ。匿名関数というかlambda式つかえと言われそうな気もしないが、pythonに至っては違いはないだろう。処理途中の関数宣言はさすがにしませんが…
以上のコードですが、書いてたときは完全無欠と思っていて確かにpython2.5などのthreadで動かすには問題はなかった。ビューティフォー…しかし、いざ2.7で動かそうとおもいきや、
pickle.PicklingError: Can't pickle <function deferred at 0x00EE9CF0>: it's not found as Async.deferred
そうかプロセス化してしまっているからunboundとかのスコープが閉じているんだ。
そうだよな、そうじゃなかったらmultiprocessing.Valueとかmultiprocessing.Arrayとか要らないよな…。
たとえ関数を展開して静的Classとして読んだとしてもlockだけはValue経由で呼ばないといけないだろう。いくらThreadと似ているといっても別物である。あぁ、失敗だ。
Arduino互換Metaboardを紐解く
安くArduinoが欲しい。そんな中でArduinoUNOとか高いし、安上がりでArduinoは手に入らないかと考えていたところ、Metaboardというマイコン一つでArduinoが作れるというのを知る。本来、ArduinoはコアとなるAVRマイコンとそのマイコンにファームウエアを書き込むためのUSB付きマイコンがセットになっているのだが、ここではV-USBベースのUSBaspをブートローダーとして機能し単体でUSBからファームウエアの書き換えが可能なArduinoを制作した。
スペックはATmega328pな20MHzであわよくば、ブートローダをブラッシュアップしようと思ったが逆にコードサイズが大きくなっただけという、どうしてこうなった。
main.c
#include <avr/io.h>
#include <avr/interrupt.h>
#include <avr/wdt.h>
#include <avr/boot.h>
#include <avr/eeprom.h>
#include <util/delay.h>

#include "usbdrv.c"

/* ------------------------------------------------------------------------ */

/* Request constants used by USBasp */
#define USBASP_FUNC_CONNECT         1
#define USBASP_FUNC_DISCONNECT      2
#define USBASP_FUNC_TRANSMIT        3
#define USBASP_FUNC_READFLASH       4
#define USBASP_FUNC_ENABLEPROG      5
#define USBASP_FUNC_WRITEFLASH      6
#define USBASP_FUNC_READEEPROM      7
#define USBASP_FUNC_WRITEEEPROM     8
#define USBASP_FUNC_SETLONGADDRESS  9

#if (FLASHEND) > 0xffff /* we need long addressing */
#define CURRENT_ADDRESS  currentAddress.l
#define addr_t uint32_t
#else
#define CURRENT_ADDRESS  currentAddress.w[0]
#define addr_t uint16_t
#endif

typedef union longConverter{
	addr_t l;
	uint16_t w[sizeof(addr_t)/2];
	uchar b[sizeof(addr_t)];
} longConverter_t;

static uchar requestBootLoaderExit;
static longConverter_t  currentAddress; /* in bytes */
static uchar bytesRemaining;
static uchar isLastPage;
static uchar currentRequest;

static const uchar signatureBytes[4] = {
#ifdef SIGNATURE_BYTES
	SIGNATURE_BYTES
#elif defined (__AVR_ATmega168__) || defined (__AVR_ATmega168P__)
	0x1e, 0x94, 0x06, 0
#elif defined (__AVR_ATmega328P__)
	0x1e, 0x95, 0x0f, 0
#else
#error "Device signature is not known, please edit main.c!"
#endif
};

/* ------------------------------------------------------------------------ */

uchar   usbFunctionSetup(uchar data[8])
{
	static uchar replyBuffer[4];
	usbRequest_t *rq = (void *)data;
	uchar len = 0;
	usbMsgPtr = replyBuffer;

	if(rq->bRequest == USBASP_FUNC_TRANSMIT){   /* emulate parts of ISP protocol */
		{
			uchar rval = 0;
			usbWord_t address;

			address.bytes[1] = rq->wValue.bytes[1];
			address.bytes[0] = rq->wIndex.bytes[0];
			if(rq->wValue.bytes[0] == 0x30){        /* read signature */
				rval = rq->wIndex.bytes[0] & 3;
				rval = signatureBytes[rval];
			} else if(rq->wValue.bytes[0] == 0xa0){  /* read EEPROM byte */
				rval = eeprom_read_byte((void *)address.word);
			} else if(rq->wValue.bytes[0] == 0xc0){  /* write EEPROM byte */
				eeprom_write_byte((void *)address.word, rq->wIndex.bytes[1]);
			} else {
				/* ignore all others, return default value == 0 */
			}
			replyBuffer[3] = rval;
			len = 4;
		}
	} else if(rq->bRequest == USBASP_FUNC_ENABLEPROG){
		len = 1;
	} else if(rq->bRequest >= USBASP_FUNC_READFLASH && rq->bRequest <= USBASP_FUNC_SETLONGADDRESS){
		currentAddress.w[0] = rq->wValue.word;
		if(rq->bRequest == USBASP_FUNC_SETLONGADDRESS){
#if (FLASHEND) > 0xffff
			currentAddress.w[1] = rq->wIndex.word;
#endif
		} else {
			bytesRemaining = rq->wLength.bytes[0];
			isLastPage = rq->wIndex.bytes[1] & 0x02;
			currentRequest = rq->bRequest;
			len = 0xff; /* hand over to usbFunctionRead() / usbFunctionWrite() */
		}
	} else if(rq->bRequest == USBASP_FUNC_DISCONNECT){
		requestBootLoaderExit = 1;      /* allow proper shutdown/close of connection */
	} else {
		/* ignore: USBASP_FUNC_CONNECT */
	}

	return len;
}

uchar usbFunctionWrite(uchar *data, uchar len)
{
	uchar   isLast;

	if(len > bytesRemaining){
		len = bytesRemaining;
	}
	bytesRemaining -= len;
	if(bytesRemaining == 0){
		isLast = 1;
	}
	if(currentRequest >= USBASP_FUNC_READEEPROM){
		{
			uchar i;
			for(i = 0; i < len; i++){
				eeprom_write_byte((void *)(currentAddress.w[0]++), *data++);
			}
		}
	} else {
		{
			uchar i;
			for(i = 0; i < len;){
				if((currentAddress.w[0] & (SPM_PAGESIZE - 1)) == 0){    /* if page start: erase */
					cli();
					boot_page_erase(CURRENT_ADDRESS);   /* erase page */
					sei();
					boot_spm_busy_wait();               /* wait until page is erased */
				}
				i += 2;
				cli();
				boot_page_fill(CURRENT_ADDRESS, *(uint16_t *)data);
				sei();
				CURRENT_ADDRESS += 2;
				data += 2;
				/* write page when we cross page boundary or we have the last partial page */
				if((currentAddress.w[0] & (SPM_PAGESIZE - 1)) == 0 || (isLast && i >= len && isLastPage)){
					cli();
					boot_page_write(CURRENT_ADDRESS - 2);
					sei();
					boot_spm_busy_wait();
					cli();
					boot_rww_enable();
					sei();
				}
			}
		}
	}

	return isLast;
}

uchar usbFunctionRead(uchar *data, uchar len)
{
	if(len > bytesRemaining){
		len = bytesRemaining;
	}
	bytesRemaining -= len;
	{
		uchar   i;
		for(i = 0; i < len; i++){
			if(currentRequest >= USBASP_FUNC_READEEPROM){
				*data = eeprom_read_byte((void *)currentAddress.w[0]);
			} else {
				*data = pgm_read_byte((void *)CURRENT_ADDRESS);
			}
			data++;
			CURRENT_ADDRESS++;
		}
	}

	return len;
}

/* ------------------------------------------------------------------------ */

static void (*nullVector)(void) __attribute__((__noreturn__));

static void __attribute__((__noreturn__)) leaveBootloader()
{
	cli();
	USB_INTR_ENABLE = 0;
	USB_INTR_CFG = 0;     /* also reset config bits */
	MCUCR = (1 << IVCE);  /* enable change of interrupt vectors */
	MCUCR = (0 << IVSEL); /* move interrupts to application flash section */
	/* We must go through a global function pointer variable instead of writing
	*  ((void (*)(void))0)();
	* because the compiler optimizes a constant 0 to "rcall 0" which is not
	* handled correctly by the assembler.
	*/
	nullVector();
}

int __attribute__((noreturn)) main(void)
{
	if(!(MCUSR & (1 << EXTRF))){ /* If this was not an external reset, ignore */
		leaveBootloader();
	}
	wdt_disable();
	MCUSR = 0;            /* clear all reset flags for next time */
	MCUCR = (1 << IVCE);  /* enable change of interrupt vectors */
	MCUCR = (1 << IVSEL); /* move interrupts to boot flash section */
	usbInit();
	usbDeviceDisconnect();
	{
		uchar i = 0;
		while(--i){
			_delay_ms(1);
		}
	}
	usbDeviceConnect();
	sei();
	for(;;) {
		if(requestBootLoaderExit){
			_delay_loop_2(65535);
			break;
		}
		usbPoll();
	}
	usbDeviceDisconnect();
	leaveBootloader();
}
usbconfig.h
/* Name: usbconfig.h
 * Project: V-USB, virtual USB port for Atmel's(r) AVR(r) microcontrollers
 * Author: Christian Starkjohann
 * Creation Date: 2005-04-01
 * Tabsize: 4
 * Copyright: (c) 2005 by OBJECTIVE DEVELOPMENT Software GmbH
 * License: GNU GPL v2 (see License.txt), GNU GPL v3 or proprietary (CommercialLicense.txt)
 * This Revision: $Id: usbconfig-prototype.h 785 2010-05-30 17:57:07Z cs $
 */

#ifndef __usbconfig_h_included__
#define __usbconfig_h_included__

/*
General Description:
This file is an example configuration (with inline documentation) for the USB
driver. It configures V-USB for USB D+ connected to Port D bit 2 (which is
also hardware interrupt 0 on many devices) and USB D- to Port D bit 4. You may
wire the lines to any other port, as long as D+ is also wired to INT0 (or any
other hardware interrupt, as long as it is the highest level interrupt, see
section at the end of this file).
+ To create your own usbconfig.h file, copy this file to your project's
+ firmware source directory) and rename it to "usbconfig.h".
+ Then edit it accordingly.
*/

/* ---------------------------- Hardware Config ---------------------------- */

#define USB_CFG_IOPORTNAME      D
/* This is the port where the USB bus is connected. When you configure it to
 * "B", the registers PORTB, PINB and DDRB will be used.
 */
#define USB_CFG_DMINUS_BIT      4
/* This is the bit number in USB_CFG_IOPORT where the USB D- line is connected.
 * This may be any bit in the port.
 */
#define USB_CFG_DPLUS_BIT       2
/* This is the bit number in USB_CFG_IOPORT where the USB D+ line is connected.
 * This may be any bit in the port. Please note that D+ must also be connected
 * to interrupt pin INT0! [You can also use other interrupts, see section
 * "Optional MCU Description" below, or you can connect D- to the interrupt, as
 * it is required if you use the USB_COUNT_SOF feature. If you use D- for the
 * interrupt, the USB interrupt will also be triggered at Start-Of-Frame
 * markers every millisecond.]
 */
#define USB_CFG_CLOCK_KHZ       (F_CPU/1000)
/* Clock rate of the AVR in kHz. Legal values are 12000, 12800, 15000, 16000,
 * 16500, 18000 and 20000. The 12.8 MHz and 16.5 MHz versions of the code
 * require no crystal, they tolerate +/- 1% deviation from the nominal
 * frequency. All other rates require a precision of 2000 ppm and thus a
 * crystal!
 * Since F_CPU should be defined to your actual clock rate anyway, you should
 * not need to modify this setting.
 */
#define USB_CFG_CHECK_CRC       0
/* Define this to 1 if you want that the driver checks integrity of incoming
 * data packets (CRC checks). CRC checks cost quite a bit of code size and are
 * currently only available for 18 MHz crystal clock. You must choose
 * USB_CFG_CLOCK_KHZ = 18000 if you enable this option.
 */

/* ----------------------- Optional Hardware Config ------------------------ */

/* #define USB_CFG_PULLUP_IOPORTNAME   D */
/* If you connect the 1.5k pullup resistor from D- to a port pin instead of
 * V+, you can connect and disconnect the device from firmware by calling
 * the macros usbDeviceConnect() and usbDeviceDisconnect() (see usbdrv.h).
 * This constant defines the port on which the pullup resistor is connected.
 */
/* #define USB_CFG_PULLUP_BIT          4 */
/* This constant defines the bit number in USB_CFG_PULLUP_IOPORT (defined
 * above) where the 1.5k pullup resistor is connected. See description
 * above for details.
 */

/* --------------------------- Functional Range ---------------------------- */

#define USB_CFG_HAVE_INTRIN_ENDPOINT    0
/* Define this to 1 if you want to compile a version with two endpoints: The
 * default control endpoint 0 and an interrupt-in endpoint (any other endpoint
 * number).
 */
#define USB_CFG_HAVE_INTRIN_ENDPOINT3   0
/* Define this to 1 if you want to compile a version with three endpoints: The
 * default control endpoint 0, an interrupt-in endpoint 3 (or the number
 * configured below) and a catch-all default interrupt-in endpoint as above.
 * You must also define USB_CFG_HAVE_INTRIN_ENDPOINT to 1 for this feature.
 */
#define USB_CFG_EP3_NUMBER              3
/* If the so-called endpoint 3 is used, it can now be configured to any other
 * endpoint number (except 0) with this macro. Default if undefined is 3.
 */
/* #define USB_INITIAL_DATATOKEN           USBPID_DATA1 */
/* The above macro defines the startup condition for data toggling on the
 * interrupt/bulk endpoints 1 and 3. Defaults to USBPID_DATA1.
 * Since the token is toggled BEFORE sending any data, the first packet is
 * sent with the oposite value of this configuration!
 */
#define USB_CFG_IMPLEMENT_HALT          0
/* Define this to 1 if you also want to implement the ENDPOINT_HALT feature
 * for endpoint 1 (interrupt endpoint). Although you may not need this feature,
 * it is required by the standard. We have made it a config option because it
 * bloats the code considerably.
 */
#define USB_CFG_SUPPRESS_INTR_CODE      0
/* Define this to 1 if you want to declare interrupt-in endpoints, but don't
 * want to send any data over them. If this macro is defined to 1, functions
 * usbSetInterrupt() and usbSetInterrupt3() are omitted. This is useful if
 * you need the interrupt-in endpoints in order to comply to an interface
 * (e.g. HID), but never want to send any data. This option saves a couple
 * of bytes in flash memory and the transmit buffers in RAM.
 */
#define USB_CFG_INTR_POLL_INTERVAL      10
/* If you compile a version with endpoint 1 (interrupt-in), this is the poll
 * interval. The value is in milliseconds and must not be less than 10 ms for
 * low speed devices.
 */
#define USB_CFG_IS_SELF_POWERED         0
/* Define this to 1 if the device has its own power supply. Set it to 0 if the
 * device is powered from the USB bus.
 */
#define USB_CFG_MAX_BUS_POWER           100
/* Set this variable to the maximum USB bus power consumption of your device.
 * The value is in milliamperes. [It will be divided by two since USB
 * communicates power requirements in units of 2 mA.]
 */
#define USB_CFG_IMPLEMENT_FN_WRITE      1
/* Set this to 1 if you want usbFunctionWrite() to be called for control-out
 * transfers. Set it to 0 if you don't need it and want to save a couple of
 * bytes.
 */
#define USB_CFG_IMPLEMENT_FN_READ       1
/* Set this to 1 if you need to send control replies which are generated
 * "on the fly" when usbFunctionRead() is called. If you only want to send
 * data from a static buffer, set it to 0 and return the data from
 * usbFunctionSetup(). This saves a couple of bytes.
 */
#define USB_CFG_IMPLEMENT_FN_WRITEOUT   0
/* Define this to 1 if you want to use interrupt-out (or bulk out) endpoints.
 * You must implement the function usbFunctionWriteOut() which receives all
 * interrupt/bulk data sent to any endpoint other than 0. The endpoint number
 * can be found in 'usbRxToken'.
 */
#define USB_CFG_HAVE_FLOWCONTROL        0
/* Define this to 1 if you want flowcontrol over USB data. See the definition
 * of the macros usbDisableAllRequests() and usbEnableAllRequests() in
 * usbdrv.h.
 */
#define USB_CFG_DRIVER_FLASH_PAGE       0
/* If the device has more than 64 kBytes of flash, define this to the 64 k page
 * where the driver's constants (descriptors) are located. Or in other words:
 * Define this to 1 for boot loaders on the ATMega128.
 */
#define USB_CFG_LONG_TRANSFERS          0
/* Define this to 1 if you want to send/receive blocks of more than 254 bytes
 * in a single control-in or control-out transfer. Note that the capability
 * for long transfers increases the driver size.
 */
/* #define USB_RX_USER_HOOK(data, len)     if(usbRxToken == (uchar)USBPID_SETUP) blinkLED(); */
/* This macro is a hook if you want to do unconventional things. If it is
 * defined, it's inserted at the beginning of received message processing.
 * If you eat the received message and don't want default processing to
 * proceed, do a return after doing your things. One possible application
 * (besides debugging) is to flash a status LED on each packet.
 */
/* #define USB_RESET_HOOK(resetStarts)     if(!resetStarts){hadUsbReset();} */
/* This macro is a hook if you need to know when an USB RESET occurs. It has
 * one parameter which distinguishes between the start of RESET state and its
 * end.
 */
/* #define USB_SET_ADDRESS_HOOK()              hadAddressAssigned(); */
/* This macro (if defined) is executed when a USB SET_ADDRESS request was
 * received.
 */
#define USB_COUNT_SOF                   0
/* define this macro to 1 if you need the global variable "usbSofCount" which
 * counts SOF packets. This feature requires that the hardware interrupt is
 * connected to D- instead of D+.
 */
/* #ifdef __ASSEMBLER__
 * macro myAssemblerMacro
 *     in      YL, TCNT0
 *     sts     timer0Snapshot, YL
 *     endm
 * #endif
 * #define USB_SOF_HOOK                    myAssemblerMacro
 * This macro (if defined) is executed in the assembler module when a
 * Start Of Frame condition is detected. It is recommended to define it to
 * the name of an assembler macro which is defined here as well so that more
 * than one assembler instruction can be used. The macro may use the register
 * YL and modify SREG. If it lasts longer than a couple of cycles, USB messages
 * immediately after an SOF pulse may be lost and must be retried by the host.
 * What can you do with this hook? Since the SOF signal occurs exactly every
 * 1 ms (unless the host is in sleep mode), you can use it to tune OSCCAL in
 * designs running on the internal RC oscillator.
 * Please note that Start Of Frame detection works only if D- is wired to the
 * interrupt, not D+. THIS IS DIFFERENT THAN MOST EXAMPLES!
 */
#define USB_CFG_CHECK_DATA_TOGGLING     0
/* define this macro to 1 if you want to filter out duplicate data packets
 * sent by the host. Duplicates occur only as a consequence of communication
 * errors, when the host does not receive an ACK. Please note that you need to
 * implement the filtering yourself in usbFunctionWriteOut() and
 * usbFunctionWrite(). Use the global usbCurrentDataToken and a static variable
 * for each control- and out-endpoint to check for duplicate packets.
 */
#define USB_CFG_HAVE_MEASURE_FRAME_LENGTH   0
/* define this macro to 1 if you want the function usbMeasureFrameLength()
 * compiled in. This function can be used to calibrate the AVR's RC oscillator.
 */
#define USB_USE_FAST_CRC                0
/* The assembler module has two implementations for the CRC algorithm. One is
 * faster, the other is smaller. This CRC routine is only used for transmitted
 * messages where timing is not critical. The faster routine needs 31 cycles
 * per byte while the smaller one needs 61 to 69 cycles. The faster routine
 * may be worth the 32 bytes bigger code size if you transmit lots of data and
 * run the AVR close to its limit.
 */

/* -------------------------- Device Description --------------------------- */

#define  USB_CFG_VENDOR_ID       0xc0, 0x16 /* = 0x16c0 = 5824 = voti.nl */
/* USB vendor ID for the device, low byte first. If you have registered your
 * own Vendor ID, define it here. Otherwise you may use one of obdev's free
 * shared VID/PID pairs. Be sure to read USB-IDs-for-free.txt for rules!
 * *** IMPORTANT NOTE ***
 * This template uses obdev's shared VID/PID pair for Vendor Class devices
 * with libusb: 0x16c0/0x5dc.  Use this VID/PID pair ONLY if you understand
 * the implications!
 */
#define  USB_CFG_DEVICE_ID       0xdc, 0x05 /* = 0x05dc = 1500 */
/* This is the ID of the product, low byte first. It is interpreted in the
 * scope of the vendor ID. If you have registered your own VID with usb.org
 * or if you have licensed a PID from somebody else, define it here. Otherwise
 * you may use one of obdev's free shared VID/PID pairs. See the file
 * USB-IDs-for-free.txt for details!
 * *** IMPORTANT NOTE ***
 * This template uses obdev's shared VID/PID pair for Vendor Class devices
 * with libusb: 0x16c0/0x5dc.  Use this VID/PID pair ONLY if you understand
 * the implications!
 */
#define USB_CFG_DEVICE_VERSION  0x02, 0x01
/* Version number of the device: Minor number first, then major number.
 */
#define USB_CFG_VENDOR_NAME 'w','w','w','.','f','i','s','c','h','l','.','d','e'
#define USB_CFG_VENDOR_NAME_LEN 13
/* These two values define the vendor name returned by the USB device. The name
 * must be given as a list of characters under single quotes. The characters
 * are interpreted as Unicode (UTF-16) entities.
 * If you don't want a vendor name string, undefine these macros.
 * ALWAYS define a vendor name containing your Internet domain name if you use
 * obdev's free shared VID/PID pair. See the file USB-IDs-for-free.txt for
 * details.
 */
#define USB_CFG_DEVICE_NAME 'U', 'S', 'B', 'a', 's', 'p'
#define USB_CFG_DEVICE_NAME_LEN 6
/* Same as above for the device name. If you don't want a device name, undefine
 * the macros. See the file USB-IDs-for-free.txt before you assign a name if
 * you use a shared VID/PID.
 */
/*#define USB_CFG_SERIAL_NUMBER   'N', 'o', 'n', 'e' */
/*#define USB_CFG_SERIAL_NUMBER_LEN   0 */
/* Same as above for the serial number. If you don't want a serial number,
 * undefine the macros.
 * It may be useful to provide the serial number through other means than at
 * compile time. See the section about descriptor properties below for how
 * to fine tune control over USB descriptors such as the string descriptor
 * for the serial number.
 */
#define USB_CFG_DEVICE_CLASS        0    /* set to 0 if deferred to interface */
#define USB_CFG_DEVICE_SUBCLASS     0
/* See USB specification if you want to conform to an existing device class.
 * Class 0xff is "vendor specific".
 */
#define USB_CFG_INTERFACE_CLASS     0   /* define class here if not at device level */
#define USB_CFG_INTERFACE_SUBCLASS  0
#define USB_CFG_INTERFACE_PROTOCOL  0
/* See USB specification if you want to conform to an existing device class or
 * protocol. The following classes must be set at interface level:
 * HID class is 3, no subclass and protocol required (but may be useful!)
 * CDC class is 2, use subclass 2 and protocol 1 for ACM
 */
/* #define USB_CFG_HID_REPORT_DESCRIPTOR_LENGTH    42 */
/* Define this to the length of the HID report descriptor, if you implement
 * an HID device. Otherwise don't define it or define it to 0.
 * If you use this define, you must add a PROGMEM character array named
 * "usbHidReportDescriptor" to your code which contains the report descriptor.
 * Don't forget to keep the array and this define in sync!
 */

/* #define USB_PUBLIC static */
/* Use the define above if you #include usbdrv.c instead of linking against it.
 * This technique saves a couple of bytes in flash memory.
 */

/* ------------------- Fine Control over USB Descriptors ------------------- */
/* If you don't want to use the driver's default USB descriptors, you can
 * provide our own. These can be provided as (1) fixed length static data in
 * flash memory, (2) fixed length static data in RAM or (3) dynamically at
 * runtime in the function usbFunctionDescriptor(). See usbdrv.h for more
 * information about this function.
 * Descriptor handling is configured through the descriptor's properties. If
 * no properties are defined or if they are 0, the default descriptor is used.
 * Possible properties are:
 *   + USB_PROP_IS_DYNAMIC: The data for the descriptor should be fetched
 *     at runtime via usbFunctionDescriptor(). If the usbMsgPtr mechanism is
 *     used, the data is in FLASH by default. Add property USB_PROP_IS_RAM if
 *     you want RAM pointers.
 *   + USB_PROP_IS_RAM: The data returned by usbFunctionDescriptor() or found
 *     in static memory is in RAM, not in flash memory.
 *   + USB_PROP_LENGTH(len): If the data is in static memory (RAM or flash),
 *     the driver must know the descriptor's length. The descriptor itself is
 *     found at the address of a well known identifier (see below).
 * List of static descriptor names (must be declared PROGMEM if in flash):
 *   char usbDescriptorDevice[];
 *   char usbDescriptorConfiguration[];
 *   char usbDescriptorHidReport[];
 *   char usbDescriptorString0[];
 *   int usbDescriptorStringVendor[];
 *   int usbDescriptorStringDevice[];
 *   int usbDescriptorStringSerialNumber[];
 * Other descriptors can't be provided statically, they must be provided
 * dynamically at runtime.
 *
 * Descriptor properties are or-ed or added together, e.g.:
 * #define USB_CFG_DESCR_PROPS_DEVICE   (USB_PROP_IS_RAM | USB_PROP_LENGTH(18))
 *
 * The following descriptors are defined:
 *   USB_CFG_DESCR_PROPS_DEVICE
 *   USB_CFG_DESCR_PROPS_CONFIGURATION
 *   USB_CFG_DESCR_PROPS_STRINGS
 *   USB_CFG_DESCR_PROPS_STRING_0
 *   USB_CFG_DESCR_PROPS_STRING_VENDOR
 *   USB_CFG_DESCR_PROPS_STRING_PRODUCT
 *   USB_CFG_DESCR_PROPS_STRING_SERIAL_NUMBER
 *   USB_CFG_DESCR_PROPS_HID
 *   USB_CFG_DESCR_PROPS_HID_REPORT
 *   USB_CFG_DESCR_PROPS_UNKNOWN (for all descriptors not handled by the driver)
 *
 * Note about string descriptors: String descriptors are not just strings, they
 * are Unicode strings prefixed with a 2 byte header. Example:
 * int  serialNumberDescriptor[] = {
 *     USB_STRING_DESCRIPTOR_HEADER(6),
 *     'S', 'e', 'r', 'i', 'a', 'l'
 * };
 */

#define USB_CFG_DESCR_PROPS_DEVICE                  0
#define USB_CFG_DESCR_PROPS_CONFIGURATION           0
#define USB_CFG_DESCR_PROPS_STRINGS                 0
#define USB_CFG_DESCR_PROPS_STRING_0                0
#define USB_CFG_DESCR_PROPS_STRING_VENDOR           0
#define USB_CFG_DESCR_PROPS_STRING_PRODUCT          0
#define USB_CFG_DESCR_PROPS_STRING_SERIAL_NUMBER    0
#define USB_CFG_DESCR_PROPS_HID                     0
#define USB_CFG_DESCR_PROPS_HID_REPORT              0
#define USB_CFG_DESCR_PROPS_UNKNOWN                 0

/* ----------------------- Optional MCU Description ------------------------ */

/* The following configurations have working defaults in usbdrv.h. You
 * usually don't need to set them explicitly. Only if you want to run
 * the driver on a device which is not yet supported or with a compiler
 * which is not fully supported (such as IAR C) or if you use a differnt
 * interrupt than INT0, you may have to define some of these.
 */
/* #define USB_INTR_CFG            MCUCR */
/* #define USB_INTR_CFG_SET        ((1 << ISC00) | (1 << ISC01)) */
/* #define USB_INTR_CFG_CLR        0 */
/* #define USB_INTR_ENABLE         GIMSK */
/* #define USB_INTR_ENABLE_BIT     INT0 */
/* #define USB_INTR_PENDING        GIFR */
/* #define USB_INTR_PENDING_BIT    INTF0 */
/* #define USB_INTR_VECTOR         INT0_vect */

#endif /* __usbconfig_h_included__ */
回路図
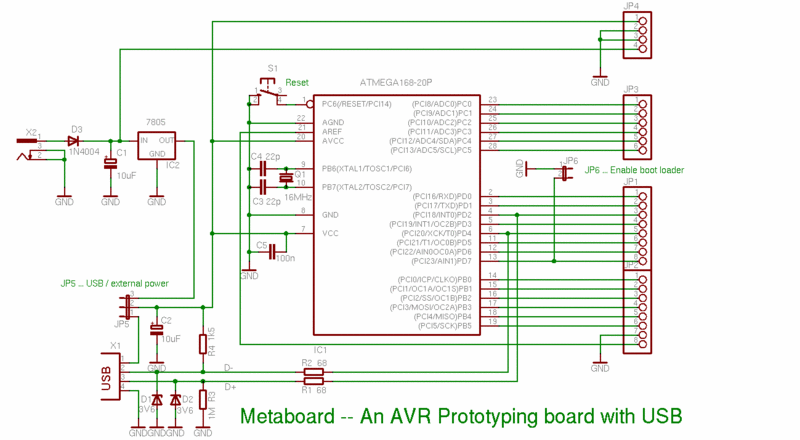
信号線とマイコンのポート接続に68Ωが使われているが、ちょっと低すぎ?V-USBじゃなくAVRUSBの名称だった時代は75Ωだった気がするのだが…。D-プルアップ用の抵抗も2.2kΩから1.5kΩに変更されている。あと、耐圧3.6Vのダイオードが使われているが、オシロでみると絶対定格の4Vを適切にクリップせずにオーバーしてしまうケースがみられる。3Vでもいいかもしれない。
AVR側のポートの閾値が5V動作の時2.5Vなのでそれを下回らない程度で十分で直流で3.3Vを超えるとUSB側の保護機能が働き動作しない場合がある。とくにダイオードを省いた構成のMetaboardをみかけるが、USBポートを痛めたくなければダイオードは必須であると思われる。
また上記のファームウエアにおいてはブートローダーを無効化設定するジャンパピンの構成を省いてある。
ソフトウエア
USBasp - USB programmer for Atmel AVR controllers - fischl.de
以上からドライバがダウンロードできます。hidaspxはAvrdudeなどの海外製書き込みソフトが対応してないですが、USBaspは対応しているので(プロジェクト的な)メンテナンスや対応ハードウエアの面で安心です。
Arduino Sketchの設定
Processing/スケッチのディレクトリ/フォルダにある。hardware/boards.txtに下記を加えます。
##############################################################
metaboard.name=Metaboard
metaboard.upload.protocol=usbasp
metaboard.upload.maximum_size=14336
metaboard.upload.speed=19200
metaboard.build.mcu=atmega328p
metaboard.build.f_cpu=20000000L
metaboard.build.core=arduino
metaboard.upload.disable_flushing=true
##############################################################
擬似自然言語検索? わかち書き検索、あいまい検索の実装まとめ
概要
実際の自然言語検索は
(検索)πはいくら? => (結果)3.1415...
(検索)answer to life the universe and everything => (結果)42
というものであるが、ここでいう自然言語検索というのは検索しようとする文字に対して検索対象となる文字列がどれほど合致しているかを調べるものである。正確には自然言語検索ではないので擬似自然言語検索、正確にはあいまい検索、わかち書き検索と呼ぶのがふさわしい。
課題と実装
例えば英数字の文字列や数字に対する検索や比較は安易であるが、一般的な日本語における比較で
問アと問イは簡単だ。
と
問アと問イは簡単だ。
は内容が同じでもFalseを返してしまうし、また表記の揺らぎとして
簡単だ、問アと問イは。
となった場合は意味は同じで文字に対して正規化を施したとしてもそのまま比較するのは難しい。実際の所は日本語形態素解析などのライブラリやAPIを施して適切な品詞を評価するわけだが、実際にMigemoやらYahooのAPIを使うのは億劫である。そこで普段慣れしたんでいるUnicodeライブラリと正規表現ライブラリを用いて簡易なあいまい検索を実装することにした。コードはpythonとする。Unicodeにおける正規化ではunicodedataにまんまnormalizeという関数がある。phpであればmb_convert_kanaあたりだろう。
#! /usr/bin/env python
# -*- coding: utf-8 -*-
import sys
reload(sys)
sys.setdefaultencoding('utf-8')

import unicodedata

if __name__ == '__main__':
	subject = u"スケジュールが切迫していたので、14時に貴社の記者が汽車で帰社した。"
	subject = unicodedata.normalize('NFKC', subject).lower()
	print subject
>>>スケジュールが切迫していたので、14時に貴社の記者が汽車で帰社した。
英文の大文字小文字に対する処理はどちらに統一するかは自由であると思う。この手の正規化で十分に半角全角大文字小文字に対するゆらぎ、はある程度解消するはずだ。次に正規表現による、わかち書きを行う。
#! /usr/bin/env python
# -*- coding: utf-8 -*-
import sys
reload(sys)
sys.setdefaultencoding('utf-8')

import re
import unicodedata

if __name__ == '__main__':
	r = re.compile(ur'([一二三四五六七八九十]+|[丁-龠]+|[ぁ-ん][ぁ-んー〜゛゜]*|[ァ-ヶ][ァ-ヶー〜゛゜]*|[0-9a-z][0-9a-z_\-]*)', re.UNICODE)
	k = re.compile(ur'[一-龠]', re.UNICODE)
	subject = u"スケジュールが切迫していたので、14時に貴社の記者が汽車で帰社した。"
	subject = unicodedata.normalize('NFKC', subject).lower()
	words = r.findall(subject)
	for x in words:
		print x,
>>>スケジュール が 切迫 していたので 14 時 に 貴社 の 記者 が 汽車 で 帰社 した
漢数字、漢字、ひらがな、カタカナ、数字にわかち書きによる分割をおこない単語に分割していく。この、わかち書きで分割された単語の部分一致によるあいまい検索がキモの部分である。以降はこのわかち書きされたデータを洗練していくだけである。
#! /usr/bin/env python
# -*- coding: utf-8 -*-
import sys
reload(sys)
sys.setdefaultencoding('utf-8')

import re
import unicodedata

if __name__ == '__main__':
	r = re.compile(ur'([一二三四五六七八九十]+|[丁-龠]+|[ぁ-ん][ぁ-んー〜゛゜]*|[ァ-ヶ][ァ-ヶー〜゛゜]*|[0-9a-z][0-9a-z_\-]*)', re.UNICODE)
	k = re.compile(ur'[一-龠]', re.UNICODE)
	subject = u"スケジュールが切迫していたので、14時に貴社の記者が汽車で帰社した。"
	subject = unicodedata.normalize('NFKC', subject).lower()
	words = r.findall(subject)
	words = [word for word in words if len(word) > 1 or k.search(word)]
	for x in words:
		print x,
>>>スケジュール 切迫 していたので 14 時 貴社 記者 汽車 帰社 した
上記で目立った処理では、漢字でない一文字の単語は削除する処理だがこれは一文字でも大きな意味をもつ漢字に対して助詞や記号によるゆらぎを抑えるためであるが、ひらがな一文字であるなら前の単語と結合するというアプローチでもいいかもしれない。
漢字でない一文字の単語は削除する場合
スケジュール 切迫 していたので 14 時 貴社 記者 汽車 帰社 した
ひらがな一文字の単語を削除せず前の単語に結合する場合。
スケジュールが 切迫 していたので 14 時に 貴社の 記者が 汽車で 帰社 した
処理が複雑になるが、多少の単語における重要度が上昇し検索精度がよくなるかもしれない。最後に実際の検索処理に入る。
#! /usr/bin/env python
# -*- coding: utf-8 -*-
import sys
reload(sys)
sys.setdefaultencoding('utf-8')

import re
import unicodedata

haystack = [
	ur'スケジュールが切迫していたので、14時に貴社の記者が汽車で帰社した。',
	ur'スケジュールの切迫により、14時に御社の記者が汽車で帰社した。',
	ur'庭には二羽鶏がいる。',
	ur'予定通り、14時に貴社の記者が汽車で帰社した。',
	ur'予定通り、14時に貴社の記者が電車で帰社した。',
]

def build(subject, type):
	r = re.compile(ur'([一二三四五六七八九十]+|[丁-龠]+|[ぁ-ん][ぁ-んー〜゛゜]*|[ァ-ヶ][ァ-ヶー〜゛゜]*|[0-9a-z][0-9a-z_\-]*)', re.UNICODE)
	k = re.compile(ur'[一-龠]', re.UNICODE)
	h = re.compile(ur'[ぁ-んー〜]', re.UNICODE)
	subject = unicodedata.normalize('NFKC', subject).lower()
	words = r.findall(subject)


	if type:
		result = [word for word in words if len(word) > 1 or k.search(word)]
	else:
		result = []
		for i, w in enumerate(words):
			if len(w) > 1 or k.search(w):
				result.append(w)
			elif i > 0 and (len(w) == 1 and h.search(w)):
				result.append(result.pop() + w)

	return result

def search(subject, database):
	# 簡易高速版 しかし配列順序が保持されない。
	# result = [(list(set(d) & set(subject)),i) for i, d in enumerate(database)]

	# 真面目に処理版
	result = []
	for i, d in enumerate(database):
		hit = []
		for s in subject:
			if s in d:
				hit.append(s)
		if hit:
			result.append((hit, i))
	return result

if __name__ == '__main__':
	print u'*漢字でない一文字の単語は削除する方法'
	subject = build(ur"スケジュールが切迫していたので、14時に貴社の記者が汽車で帰社した。", True)
	database = [build(v, True) for v in haystack]
	result = search(subject, database)
	for r in result:
			print haystack[r[1]]
			print ur'A', '->', ((len(r''.join(r[0]))*1.0) / (len(r''.join(subject))*1.0)) * 100.0, ur'%'
			print ur'B', '->', (len(r[0])*1.0) / (len(subject)*1.0) * 100.0, ur'%'

	print u'\n'

	print u'*ひらがな一文字の単語を削除せず前の単語に結合する方法'
	subject = build(ur"スケジュールが切迫していたので、14時に貴社の記者が汽車で帰社した。", False)
	database = [build(v, False) for v in haystack]
	result = search(subject, database)
	for r in result:
			print haystack[r[1]]
			print ur'A', '->', ((len(r''.join(r[0]))*1.0) / (len(r''.join(subject))*1.0)) * 100.0, ur'%'
			print ur'B', '->', (len(r[0])*1.0) / (len(subject)*1.0) * 100.0, ur'%'
>>>
*漢字でない一文字の単語は削除する方法
スケジュールが切迫していたので、14時に貴社の記者が汽車で帰社した。
A -> 100.0 %
B -> 100.0 %
スケジュールの切迫により、14時に御社の記者が汽車で帰社した。
A -> 70.3703703704 %
B -> 80.0 %
予定通り、14時に貴社の記者が汽車で帰社した。
A -> 48.1481481481 %
B -> 70.0 %
予定通り、14時に貴社の記者が電車で帰社した。
A -> 40.7407407407 %
B -> 60.0 %


*ひらがな一文字の単語を削除せず前の単語に結合する方法
スケジュールが切迫していたので、14時に貴社の記者が汽車で帰社した。
A -> 100.0 %
B -> 100.0 %
スケジュールの切迫により、14時に御社の記者が汽車で帰社した。
A -> 50.0 %
B -> 70.0 %
予定通り、14時に貴社の記者が汽車で帰社した。
A -> 53.125 %
B -> 70.0 %
予定通り、14時に貴社の記者が電車で帰社した。
A -> 43.75 %
B -> 60.0 %
Aはヒット単語数の文字数による整合性、Bにはヒット単語数の整合性である。漢字でない一文字の単語を削除する場合の比較ではヒット単語数による整合性のほうが妥当性があるのだが、ひらがな一文字の単語を削除せず前の単語に結合する場合には文字数の多さが重要性の高さに関連しているのか、ヒット単語数による文字数による整合性のほうが良い結果が出るようであるのが興味深い。また助詞による表記のゆれによるヒット率の低下がケースによっては極端に見られる。大体において整合性が50%を超える場合は十分に関連性が高いと見えるだろう。今回は配列からinによる条件式を用いたが、SQLにおけるINでも同様の扱いが可能であると思う。setを用いた簡易処理版はpythonにおけるset型は配列順序が保持されず単語出現順位によるマッチングが利用できなくるという点が残念だ。
以上が日本語によるわかち書き検索、あいまい検索を用いた検索システムであるが、Unicodeだろうが、正規表現だろうが、日本語処理は難しく奥が深い。
V-USBの使い方まとめ
HIDaspxのコピーが手に入ったので年末年始の宿題として2台拝借。
これを使ってV-USBやUSB1.1 LowSpeedについて勉強しようとする魂胆。
概要・HIDaspxについて
http://www.binzume.net/library/avr_hidasp.html
上記のサイトの人が作ったHIDaspをブラッシュアップして高速化、使いやすくした物。またはそのカスタム品。
ブラッシュアップ、カスタムについては下記のサイトを参照してください。
http://hp.vector.co.jp/authors/VA000177/html/A3C8A3C9A3C4A3E1A3F3A3F0A3F8.html
http://www-ice.yamagata-cit.ac.jp/ken/senshu/sitedev/index.php?AVR%2FHIDaspx00
概要・USB
USB1.1 LowSpeedについては以下の通り。
通信線のD-ピンをプルアップすることによってホスト側にLowSpeedと区別させる。
NRZIによる符号化、ヘッダやサムチェック(CRC)、ACKを含めた上で1.5Mbpsの通信速度。もちろん実際に送信できるデータ量と通信速度は遅くなる。
ホスト側のコントローラによって通信速度が違い、Intel, VIAのUHCIでは速度が最悪1/4まで低下する、Microsoft策定のNECら率いるOHCIではそうでもない。
上記の問題でUSB2.0のEHCIではUSB1.1のハブをかませる事によって速度低下を防ぐことができる。
論理的にはPCとデバイスをつなぐ線をパイプとよびFIFOとする。パイプ末端とエンドポイントと呼ぶ。
エンドポイント0はコントロール転送にも用いられFeatureと定義されてWindowsではHidD_GetFeature(), HidD_SetFeature()関数を用いて通信する。
その他のエンドポイントはインタラプト通信に使われInputもしくはOutputと定義され、WindowsではWriteFile()もしくはReadFile()関数を用いて通信を行う。
- スペック
- (実質)半二重通信
- データ量 1〜64byte
- パケット長 8byte
- ポーリング間隔
- コントロール転送では通信間隔を1ms以内としインタラプト転送では最低10msとする。HID-CDCでは例外的にエンドポイント3を用いてインタラプト転送でも通信間隔を最低3ms間隔とする場合がある。
概要・V-USB
http://www.obdev.at/products/vusb/index.html
元AVR-USB、本家ATmelの商標とかぶるためにV-USBとした。
USBの通信線をAVRの外部割り込みポートにつなぐ事によりUSB1.1 LowSpeedを扱えるようにしたUSBスタックである。
ライセンスはGPL、またGPLを使うに限り用意されたベンダーIDを用いることができるがベンダーネームをobdev.atから書き換えてはならないとしている。
実装・デバイス側
実装
大体、実装できるのは以下である
- Standard HID class device
- マウスやキーボードなどの仕様によって実装。ドライバいらず。
- CDC class devices
- USBシリアルなどの実装。OS側でデバイスドライバを補完しなくてはならない。(COMポートのバインドなど)
- その他のHIDデバイス
- HIDデバイスではあるが、通信内容は自分で定義。ドライバいらずだが、操作するアプリは自前で作る。
何を選ぶかによって設定方法は変わるがここではその他のHIDデバイスを作成する。
ハードウエア
AVRライターのHIDaspxのハードウエア構成は以下である。
HIDaspxのファームウエアのソースコードから引用した。
         ATtiny2313
         ___    ___
RESET    [1  |__| 20] Vcc
PD0(NC)  [2       19] PB7(SCK)
PD1(NC)  [3       18] PB6(MISO)
XTAL2    [4       17] PB5(MOSI)
XTAL1    [5       16] PB4(RST)
PD2(12M) [6       15] PB3(BUSY LED)
PD3      [7       14] PB2(READY LED)
PD4      [8       13] PB1(NC)
PD5(PUP) [9       12] PB0(NC)
GND      [10      11] PD6(NC)
         ~~~~~~~~~~~

   ---------------------------------------
   SPI:     PB7-4 ===> [Target AVR Device](MISOとMOSIは交差)
   USB:     PD4   ===> USB D-
            PD3   ===> USB D+
            PD5   ===> USB D- PULL UP
   XTAL:    XTAL1,2 => Crystal 12MHz
   PD2:     Clock Output(12MHz)
   ---------------------------------------
気をつけなければならないところはPD5によってD-がプルアップされた上でPD4に直接つながれていて、D+はPD2のINT0でなくPD3のINT1で外部入力割り込みされていることである。
また12MHzで動かす上では必ずしもクリスタルやセラロックは必要ではない。
内発8MHz出力の校正用レジスタを変更することによって最大12.8MHzまでクロックアップすることができる。
16MHzのクリスタルを用いることが一番安定していてコード量も小さくなるがHIDaspxでは内発でないクリスタル12MHzを使用している。
CPUはATmelのATtiny2313を用いていてPORTBの8ピンはUSB動作においては使用していない。
V-USB・設定(usbconfig.h)
usbconfig-prototype.hをusbconfig.hにリネームして使用する。
#define USB_CFG_DPLUS_BIT 3
上記のとおりD+ピンはPORTDのPD3に接続されているのでここは3にする。
#define USB_CFG_PULLUP_IOPORTNAME D
何がDなのかというとPORTDのDである。コメントを外しておく。
#define USB_CFG_PULLUP_BIT 5
上記のとおりD-をプルアップしているのはPD5なのでここは5としてコメントを外しておく。
#define USB_CFG_HAVE_INTRIN_ENDPOINT 1
エンドポイントを用いるので1に。
#define USB_CFG_IMPLEMENT_FN_WRITE 1
コントロール転送でデータを受信できるようにするために1とする。ファームウエア内でusbFunctionWrite()関数がコールバックされる。
#define USB_CFG_IMPLEMENT_FN_READ 1
コントロール転送でデータを受信できるようにするために1とする。ファームウエア内でusbFunctionRead()関数がコールバックされる。
#define USB_CFG_IMPLEMENT_FN_WRITEOUT 0
インタラプト転送でデータを受信したときにファームウエア内のusbFunctionWriteOut()関数をコールバックするための設定。1で有効となる。
#define USB_USE_FAST_CRC 0
CRC計算を通常の計算にくらべてほぼ2分の1にする設定だが、コード量が32byte増える諸刃の剣。ポーリング、割り込み時間を低減したい場合に使用する?
#define USB_CFG_DEVICE_CLASS 0
HIDデバイスとして認識させるために0とする。
#define USB_CFG_INTERFACE_CLASS     3
#define USB_CFG_INTERFACE_SUBCLASS  0
#define USB_CFG_INTERFACE_PROTOCOL  0
HIDクラスとして認識させるためにUSB_CFG_INTERFACE_CLASSは3、残りを0とする。
#define USB_INTR_CFG_SET        ((1 << ISC10) | (1 << ISC11))
#define USB_INTR_ENABLE_BIT     INT1
#define USB_INTR_PENDING_BIT    INTF1
#define USB_INTR_VECTOR         INT1_vect
V-USBは外部割り込みポートを用いて動作するが、基本はINT0の割り込みを用いる。HIDaspxはINT1を使うために上記のように設定する。
#define USB_CFG_HID_REPORT_DESCRIPTOR_LENGTH 22
最後に説明するが、設定項目は最後にはない。HIDデバイスは自らの仕様をホストとなるコンピュータに提示するためにHIDレポートディスクリプタという構造体を用いる。その構造体のサイズをバイトで記述する。ここでは22とした。
V-USB・設定(メイン)
インクルードしなければならない最低限のヘッダファイルは以下である。
#include <avr/io.h>
#include <avr/interrupt.h>
#include <avr/pgmspace.h>
上記でも記したがHIDデバイスは自らの仕様、つまり通信フォーマットをホストコンピュータに提示するためにレポートディスクリプタが必要である。
もし、レポートディスクリプタを設定しない場合はHIDデバイスであったとしてもWindowsであれば自前のデバイスドライバを作らなければならない。
PROGMEM char usbHidReportDescriptor[22] = {    /* USB report descriptor */
    0x06, 0x00, 0xff,              // USAGE_PAGE (Generic Desktop)
    0x09, 0x01,                    // USAGE (Vendor Usage 1)
    0xa1, 0x01,                    // COLLECTION (Application)
    0x15, 0x00,                    //   LOGICAL_MINIMUM (0)
    0x26, 0xff, 0x00,              //   LOGICAL_MAXIMUM (255)
    0x75, 0x08,                    //   REPORT_SIZE (8)
    0x95, 0x08,                    //   REPORT_COUNT (8) <--- データサイズ(byte)
    0x09, 0x00,                    //   USAGE (Undefined)
    0xb2, 0x02, 0x01,              //   FEATURE (Data,Var,Abs,Buf)
    0xc0                           // END_COLLECTION
};
コントロール転送において8byteのデータをやりとりするためのレポートディスクリプタの例が以上である。
パケット長が8byteなのはV-USB上では仕様で変更できない。
なのでデータサイズを8byte以上に設定すると8byteに区切って処理しなければならないので8の倍数で設定すると実装が楽である。
またコントロール転送では一回の通信時間を1ms間隔とするので送るデータサイズが大きいほど見かけの通信速度が早くなる。
inline uchar usbFunctionRead(uchar *data, uchar len)
{
	// 送信すべきデータのアドレスをdataにセット。
	return 1; // 処理が終了すれば1を返す。
}

inline uchar usbFunctionWrite(uchar *data, uchar len)
{
	// 受信したデータをdataから処理する。
	return 1; // 処理が終了すれば1を返す。
}

inline usbMsgLen_t usbFunctionSetup(uchar data[8])
{
	usbRequest_t *rq = (void *)data;

	if((rq->bmRequestType & USBRQ_TYPE_MASK) == USBRQ_TYPE_CLASS){
		if(rq->bRequest == USBRQ_HID_GET_REPORT){ // usbFunctionRead()でデータ送信命令が来たフラグ。
			return USB_NO_MSG; // USB_NO_MSGと返すことによってこの関数終了後にusbFunctionRead()が呼ばれる
		} else if(rq->bRequest == USBRQ_HID_SET_REPORT){ // usbFunctionWrite()でデータの受信が来たフラグ。
			return USB_NO_MSG; // USB_NO_MSGと返すことによってこの関数終了後にusbFunctionWrite()が呼ばれる
		}
	}

	return 0;
}
コントロール転送に限らずエンドポイント0で処理されなければならないデータは皆usbFunctionSetup()関数で適切に処理されなければならない。
USBRQ_HID_GET_REPORTやUSBRQ_HID_SET_REPORTではコントロール転送に必要な処理が渡されUSB_NO_MSGを返すことによってusbFunctionRead()やusbFunctionWrite()に処理が移る。
実装によっては他にも必要なフラグがあるが、例えばUSBRQ_HID_GET_IDLEやUSBRQ_HID_SET_IDLE等などではインタラプト転送におけるポーリング間隔を指定もしくは設定するものがある。
以下、V-USBのマウス実装の例をあげる。
usbMsgLen_t usbFunctionSetup(uchar data[8])
{
	usbRequest_t *rq = (void *)data;

	/* The following requests are never used. But since they are required by
	* the specification, we implement them in this example.
	*/
	if((rq->bmRequestType & USBRQ_TYPE_MASK) == USBRQ_TYPE_CLASS){    /* class request type */
		DBG1(0x50, &rq->bRequest, 1);   /* debug output: print our request */
		if(rq->bRequest == USBRQ_HID_GET_REPORT){  /* wValue: ReportType (highbyte), ReportID (lowbyte) */
			/* we only have one report type, so don't look at wValue */
			usbMsgPtr = (void *)&reportBuffer;
			return sizeof(reportBuffer);
		} else if(rq->bRequest == USBRQ_HID_GET_IDLE){
			usbMsgPtr = &idleRate;
			return 1;
		} else if(rq->bRequest == USBRQ_HID_SET_IDLE){
			idleRate = rq->wValue.bytes[1];
		}
	} else {
		/* no vendor specific requests implemented */
	}
	return 0;   /* default for not implemented requests: return no data back to host */
}
usbFunctionSetup()で0が帰った場合はホストに対して返答を行わないが1以上を設定するとusbMsgPtrのアドレスのデータを設定した値だけバイト数で送信される。
USBRQ_HID_SET_IDLEでは設定されるべき値はusbRequest_tのwValue.bytes[1]に含まれるがカスタムなUSBリクエストでは任意のバリューを設定できるはず。
USBRQ_HID_GET_REPORTやUSBRQ_HID_SET_REPORTでは何が入っているかは未確認。レポートID?
void main(void)
{
	PORTD = ((1<<PD6)|(1<<PD5)|(1<<PD2)|(1<<PD1)|(1<<PD0));
	DDRD = ~(USBMASK|(1<<PD6)|(1<<PD2)|(1<<PD1)|(1<<PD0));

	usbInit();
	usbDeviceDisconnect();
	{
		uchar i = 0;
		while(--i){
			_delay_ms(1);
		}
	}
	usbDeviceConnect();
	sei();
	for(;;){
		usbPoll();
		/*
		char interruptSendData[] = "12345678"; // インタラプト転送データサイズに合わせる
		if(usbInterruptIsReady()){
			usbSetInterrupt((void *)&interruptSendData, sizeof(interruptSendData));
		}
		*/
	}
}
最低限のmain関数は以上。
インタラプト転送における送信は簡単だが、使用するにはもちろんレポートディスクリプタにインタラプト転送における送信設定を記述しなければならない。
PROGMEM char usbHidReportDescriptor[] = {
    0x06, 0x00, 0xff,              // USAGE_PAGE (Generic Desktop)
    0x09, 0x01,                    // USAGE (Vendor Usage 1)
    0xa1, 0x01,                    // COLLECTION (Application)
    0x15, 0x00,                    //   LOGICAL_MINIMUM (0) // コントロール転送用設定ここから
    0x26, 0xff, 0x00,              //   LOGICAL_MAXIMUM (255)
    0x75, 0x08,                    //   REPORT_SIZE (8)
    0x95, 0x08,                    //   REPORT_COUNT (8) <--- コントロール転送データサイズ
    0x09, 0x00,                    //   USAGE (Undefined)
    0xb2, 0x02, 0x01,              //   FEATURE (Data,Var,Abs,Buf)  // コントロール転送用設定ここまで
    0x15, 0x00,                    //   LOGICAL_MINIMUM (0) // インタラプト送信用設定ここから
    0x26, 0xff, 0x00,              //   LOGICAL_MAXIMUM (255)
    0x75, 0x08,                    //   REPORT_SIZE (8)
    0x95, 0x08,                    //   REPORT_COUNT (8) <--- インタラプト転送データサイズ
    0x09, 0x00,                    //   USAGE (Undefined)
    0x81, 0x02,                    //   INPUT (Data,Var,Abs) // インタラプト送信用設定ここまで
    0xc0                           // END_COLLECTION
};
もちろんUSB_CFG_HID_REPORT_DESCRIPTOR_LENGTHの値を適当な値に変えておくこと。
インタラプト転送の送信をホスト側で受信するにはWindowsであればReadFile()を用いる。
ReadFile()はデータを受信するまで処理をブロックするが、ReadFile()が用意されていない状態でデバイス側がデータを送信してもデータは破棄されてしまうので注意。
AVR-GCCについて
環境はAVR StudioとAVR Toolchain Installerである。
現在AVR Toolchain Installerで提供されるAVR-GCCのバージョンは4.4.3である。
コード量が増えるといってVer4のGCCを避ける人がいるかも知れないがVer4でもコードが小さくなる設定があるので此処に書く。
コンパイルオプション
-fdata-sections
-ffunction-sections
余分な関数や変数がロードされなくてすっきり!
-ffreestanding
宣言にint __attribute__((noreturn)) main(void);
追加でmain関数のreturnによるレジスタ処理を抑制
-fno-schedule-insns2
プリフェッチのある深いパイプライン向けのロード/ストア命令最適化なのでAVRでは逆にUSIの実装などでは逆に邪魔。
-mcall-prologues
AVR向け関数呼び出しの最適化
-fno-tree-scev-cprop
-fno-split-wide-types
最適化レベルOsでは含まれないコード展開を抑制

リンカオプション
-Wl,--relax,--gc-sections
AVR-GCC用にも--relaxが用意されているらしい。
ホスト側・実装
Windowsにおいて必要なDLLではhid.dll, setupapi.dll, kernel32.dllの三つ。
libusbやwinusbなどのライブラリもあるが、バグいろいろやり方いろいろなのでMinGWとwin32api(DDK含む)で開発。
MFCだのなんだの開発するにはC#だのpythonでのバインドとかはやっぱり邪道で男は黙ってVCかMinGWとwin32apiが楽だと思った。
http://www.crimson-systems.com/tips/t085a.htm
以上のサイトを参考に以下にソースを提示する。
#include <stdio.h>
#include <stdlib.h>
#include <windows.h>
#include <setupapi.h>
#include <ddk/hidsdi.h>

#pragma comment(lib, "setupapi.lib")
#pragma comment(lib, "hid.lib")

HANDLE __stdcall HIDOpen(int iVendorID, int iProductID)
{
	GUID hidGuid;
	HANDLE hDevHandle = NULL;
	HDEVINFO hDevInfo;
	HIDD_ATTRIBUTES Attributes;
	PSP_DEVICE_INTERFACE_DETAIL_DATA pspDidd;
	SP_DEVICE_INTERFACE_DATA spDid;

	HidD_GetHidGuid(&hidGuid);
	hDevInfo = SetupDiGetClassDevs(&hidGuid, NULL, NULL, DIGCF_PRESENT|DIGCF_DEVICEINTERFACE|DIGCF_ALLCLASSES);
	{
		USHORT i;
		for(i = 0; i < 128;i++){
			memset(&spDid, 0, sizeof(SP_DEVICE_INTERFACE_DATA)); // spDid Clear;
			spDid.cbSize = sizeof(SP_DEVICE_INTERFACE_DATA);
			if(!SetupDiEnumDeviceInterfaces(hDevInfo, NULL, &hidGuid, i, &spDid)) continue;
			DWORD dwRequiredLength = 0;
			SetupDiGetDeviceInterfaceDetail(hDevInfo, &spDid, NULL, 0, &dwRequiredLength, NULL);
			pspDidd = (PSP_DEVICE_INTERFACE_DETAIL_DATA)malloc(dwRequiredLength);
			pspDidd->cbSize = sizeof(SP_DEVICE_INTERFACE_DETAIL_DATA);
			if(SetupDiGetDeviceInterfaceDetail(hDevInfo, &spDid, pspDidd, dwRequiredLength, &dwRequiredLength, NULL)){
				hDevHandle = CreateFile(pspDidd->DevicePath, GENERIC_READ|GENERIC_WRITE, FILE_SHARE_READ|FILE_SHARE_WRITE, NULL, OPEN_EXISTING, 0, NULL);
				if(hDevHandle != INVALID_HANDLE_VALUE){
					Attributes.Size = sizeof(Attributes);
					if(HidD_GetAttributes(hDevHandle, &Attributes)){
						if(iVendorID == Attributes.VendorID && iProductID == Attributes.ProductID){
							free(pspDidd);
							break;
						}
					}
					CloseHandle(hDevHandle);
				}
			}
			free(pspDidd);
		}
	}
	return hDevHandle;
}
ベンダーIDとプロダクトIDを用いて指定のHIDデバイスのファイルハンドラを取得する。
もちろん使用後のファイルハンドルはCloseHandle()で処理すべきである。
for文を127回を上限としているのは接続できるUSBデバイスが127個以下と規定しているからであるが、USB外のHIDデバイス(Bluetoothなど)ではこの限りではない。
HIDP_CAPS __stdcall HIDGetCaps(HANDLE hDevHandle)
{
	PHIDP_PREPARSED_DATA lpData;
	HIDP_CAPS caps;

	if(HidD_GetPreparsedData(hDevHandle, &lpData)){
		HidP_GetCaps(lpData, &caps);
	}
	HidD_FreePreparsedData(lpData);

	return caps;
}
レポートディスクリプタからHIDデバイスのスペックを取得する関数である。
HIDP_CAPSにおける、InputReportByteLength, OutputReportByteLength, FeatureReportByteLengthから通信に使用するバッファ長を求めるために用いる。
BOOL __stdcall HIDSetFeature(HANDLE hDevHandle, PVOID data, ULONG length, UCHAR nReportID)
{
	BOOL bResult;

	if(length <= 1){
		bResult = HidD_SetFeature(hDevHandle, &nReportID, length);
	} else {
		memmove(data+1, data, length - sizeof(UCHAR));
		((UCHAR *)data)[0] = nReportID;
		bResult = HidD_SetFeature(hDevHandle, data, length);
	}

	return bResult;
}
コントロール転送においてHIDデバイス対してデータを送信する関数である。
レポートディスクリプタで設定したデータサイズよりも1byte大きくHIDP_CAPSのFeatureReportByteLengthから報告されるが、最初にセットする1byteはレポートIDに使用する。
MinGW(DLL)
DLL化したのは他のアプリ、C#やpythonからでも操作できるようにした意思からであるが、MinGWにおけるDLL作成のメモを期する。
ずばり言えばリンカオプションに
-Wl,--dll,--add-stdcall-alias,--kill-at,--enable-stdcall-fixup
あとは関数にstdcallを宣言すればDLLが出来上がる。
DllMain()関数はなくても勝手に処理してくれるみたいだ。
本来はエクスポートすべき関数を指定するdefファイルを真面目に記述する必要があるが、ここでは手抜き。
Pythonから使う
#!
#
from ctypes import *
from ctypes.wintypes import c_char, ULONG, BOOLEAN, BYTE, WORD, DWORD

class HIDD_ATTRIBUTES(Structure):
	_fields_ = [
		("cb_size", DWORD),
		("vendor_id", c_ushort),
		("product_id", c_ushort),
		("version_number", c_ushort)
	]

class HIDP_CAPS(Structure):
	_fields_ = [
		("usage", c_ushort),
		("usage_page", c_ushort),
		("input_report_byte_length", c_ushort),
		("output_report_byte_length", c_ushort),
		("feature_report_byte_length", c_ushort),
		("reserved", c_ushort * 17),
		("number_link_collection_nodes", c_ushort),
		("number_input_button_caps", c_ushort),
		("number_input_value_caps", c_ushort),
		("number_input_data_indices", c_ushort),
		("number_output_button_caps", c_ushort),
		("number_output_value_caps", c_ushort),
		("number_output_data_indices", c_ushort),
		("number_feature_button_caps", c_ushort),
		("number_feature_value_caps", c_ushort),
		("number_feature_data_indices", c_ushort)
	]

hid = windll.LoadLibrary(r"HIDDevice.dll")
dev = hid.HIDOpen(5824,1503)
if dev != -1:
	hid.HIDGetAttrbutes.restype = HIDD_ATTRIBUTES
	print "Product:", hid.HIDGetAttrbutes(dev).product_id
	hid.HIDGetCaps.restype = HIDP_CAPS
	res = hid.HIDGetCaps(dev)
	print "F:", res.feature_report_byte_length, res.number_link_collection_nodes, res.number_feature_value_caps, res.number_feature_data_indices
	hid.HIDClose(dev)
ここまでCでラッピングしておけばpythonからの操作も楽にできる。
最後に
今回はHIDaspxを2台つかい片方をライタ、もう片方を実験台として使用しました。
HIDaspxではHIDmonというPCからAVR内部のレジスタを操作する機能があるが、I/OやPWMなど単体で動くペリフェラルの他にUARTやUSIなど内部で完結していないと実装が難しい処理が多くある。
これらを自らファームで実装出来ればそれらのペリフェラルを使い倒せるのではないか。
そもそもFT232RLなどの表面実装パッケージで値段が高いUSBtoシリアルドライバや、たとえDIPパッケージでもマイコンにADM3202とかのインターフェイスドライバにシリアルポートをハンダ付けとかにくらべれば多少頭をひねるだけでPCとマイコンの通信が出来るのならいろいろ楽しく遊べるのではないかなとかおもうお正月休みでした。
